AI
June 21, 2026

Generic AI isn’t Good Enough for Clinical Trial Finance. Here’s Why.
Key takeaways

This is part 3 of a series on How to successfully implement AI. Part 1 covered what AI is. Part 2 covered how Condor uses AI to produce numbers you can trust. This one covers why generic AI can’t do clinical trial finance.

Finance teams across biopharma are connecting ChatGPT and Claude to their clinical trial data and asking for accruals, variance explanations, and spend forecasts. Generic AI is excellent at conversational finance work: synthesizing documents, drafting memos, ad hoc analysis, and finance teams should be using it today.

But as many companies are finding out, building an AI interface is easy. The hard part is the underlying context engineering, validation, domain expertise, and operational understanding required to make outputs trustworthy and actionable. 

Clinical trial finance is a reasoning problem over a structured system of record, and generic AI lacks the architecture required to reason reliably over that system. 

That’s because generic AI wasn’t purpose-built for the complexity of clinical trial finance. As a result, it often produces inconsistent results on subjective estimates (aka clinical accruals). Here are the three reasons why generic AI isn't precise enough for clinical trial finance, and what the right architecture looks like. 

1. It doesn’t understand the business of clinical R&D

As finance leaders, we know a simple truth: before you can understand the finances, you must understand the business. Generic AI is no different. 

Every number depends on protocols, patient enrollment, site activity, vendor contracts, change orders, milestones, pass-through costs, and accounting policies. To understand the financial outcome, you first need to understand the operational reality driving it.

Generic AI reasons over text. It does not understand how your trial operates, or have the necessary domain context. Clinical trial finance is a relational problem — a web of interdependent contracts, protocol events, accounting rules, and cost structures that must all align before a number is trustworthy.

You can add specific business and clinical context to help your analysis. But as you read below, you’ll see that’s not enough. This is why standard accounting reconciliation processes are good candidates for generic AI, but they can be dangerous when used for a deeply specialized and industry-specific workflow.

For example, if you ask it what "pass-through costs" are, it will know the dictionary definition, and it might be able to make a guess on how it applies. It doesn’t know the nuances within the pass-through costs, why they’ve been contracted, what it means to the clinical trial itself, and what operational drivers affect those costs. 

Generic AI will also understand clinical accruals or forecasting very broadly. But you’ll have to spend a lot of time engineering the context to understand what happens on a given protocol, what the assessments are, why they matter, the logic behind visits in the EDC, what the CROs are contractually doing, what the different imaging vendors are doing, and the inflection points you're executing against. 

Let’s say you initially engineer this context and map it to your business. Your model will still drift without grounding. 

2. It has no grounding, so it hallucinates and drifts

After the context, the next hurdle is grounding and drift.  

A hallucination is when generic AI generates information that is factually incorrect, fabricated, or nonsensical, but presents it with apparent confidence, as if it were true. For example, the analysis tells you “The CRO amendment increased costs by $2.3M”, but no amendment exists. Hallucinations aren’t a bug that gets fixed. They’re a structural property of how generic AI works. It has no mechanism to check whether what it's saying is true. And that's a gap.

Drift is another problem. It’s gradual degradation or shift in an AI model's performance, behavior, or outputs over time. The answer can sound perfectly reasonable, use real information, and still solve the wrong problem. For example, the analysis started answering your question, "How much cash do we need to reach the last patient dosed?", and 10 steps later it’s optimizing the study timeline rather than answering the cash requirement question. The numbers may be real. The model is just solving the wrong problem.

Both failures stem from the same issue: the model has no source of truth. Grounding is what closes this gap.

Your enrollment and site administration lives in clinical systems, contracts in executed agreements live in multiple systems, your budget and forecast may live in different systems or on a spreadsheet — none sharing a data model. They need to share a data model and know how to relate with one another in order to be precise and effective. This is what enables the lineage (or audit trail described below).

A grounded system ties every claim to a structured source of truth: an ontology defining what entities exist, a knowledge graph defining how they relate, and deterministic rules the output must satisfy before providing probabilistic results.  

Generic AI has none of this. Working from a flat export, the model has no way to know what it doesn't know. The result is confident, specific, and unverifiable (or unauditable). In a regulated industry that needs reliability, consistency and accuracy, that’s a very dangerous kind of wrong. 

3. It’s missing lineage (aka audit trail): It can't explain where the answer came from 

Here's the ultimate test: ask any AI system to show its work; not just the answer. Show the exact contracts, enrollment data, site activity, assumptions, accounting policies, and calculations that produced the number. Show how they relate to one another. Show what changed since last month. Show what drove the variance.

Generic AI can't do this.

Even when it produces the correct answer, it cannot reliably explain the chain of reasoning that led there. Its outputs are generated through statistical inference, not a documented chain of evidence. There is no persistent record connecting the underlying clinical and financial data to the final result.

This becomes a major problem in clinical trial finance because trust isn't created by the number itself. Trust comes from understanding how the number was produced.

Every accrual, forecast, and scenario depends on hundreds of interconnected assumptions across protocols, contracts, enrollment, site activity, vendor spend, accounting policy, and financial controls. If you cannot trace the output back through those relationships, you cannot validate it, defend it, or audit it.

This is where lineage becomes essential.

Lineage creates a complete chain of custody from source data to financial outcome. It shows which systems were used, how the data was mapped, which business rules were applied, what assumptions were made, and how every calculation was derived. When an executive asks a question, the answer isn't simply generated — it is supported.

In regulated industries, explainability isn't optional. Auditors require it, controllers depend on it, and regulators expect it. And finance leaders need it before they can trust AI with material decisions.

Without lineage, AI produces answers. With lineage, AI produces evidence.

What the right architecture looks like

Condor was built to solve exactly these three problems. 

Domain context is built in. Condor was designed specifically for clinical trial finance, with years of clinical and financial knowledge embedded into its foundation. Condor's platform is built on proprietary clinical and financial ontologies that understand the relationships between protocols, enrollment, site activity, vendor contracts, budgets, forecasts, and accounting rules because those relationships are native to the system; not added later through prompts or manual configuration. These ontologies were developed over years with Big 4 accounting firms; not configured after the fact, but architected into the foundation. When Condor calculates an accrual, it is applying rules that reflect how clinical trial finance actually works.

Grounding mitigates hallucination and drift. The knowledge graph in Condor continuously connects your live clinical, operational and financial data across the systems biopharma companies already use — CTMS, EDC, IVRS, CRO contracts — to a structured model of how that data relates to financial obligations. There is no gap-filling. When enrollment changes, sites activate, milestones are achieved, or change orders are approved, the financial impact is reflected automatically. The platform isn't inferring what happened. It understands what happened and how it affects the forecast, accrual, and budget. The AI reasons against a ground truth it can prove.

Every number is explainable and comes with an audit trail. Finance teams can trace results back to the underlying contracts, operational activities, assumptions, and accounting rules that produced them. The platform doesn't just provide an answer; it provides the evidence behind the answer.

The difference between generic AI and a purpose-built clinical financial intelligence platform isn't a feature gap. It's an architecture gap. One was designed to generate plausible answers. The other was designed to produce numbers you can prove and explain. 

In clinical trial finance, that distinction matters. It determines whether forecasts are credible, whether accruals are defensible, whether auditors can validate the process, and ultimately whether management teams have the confidence to make the right business decisions.

The good news is that these technologies are complementary. Generic AI is excellent for research, analysis, and productivity. Purpose-built clinical financial intelligence platforms provide the trusted data and operational foundation those tools need to be effective so they can operate with confidence and bring therapies to patients faster and more cost effectively. 

Condor can help you elevate your R&D finance function into an AI-native one by enriching your generic AI with domain context, grounding it to prevent hallucinations and drift, and creating an audit trail. Schedule some time with our experts to learn more

Condor is the Financial Intelligence Platform for life sciences R&D. Learn more at condorsoftware.com.
Read more

AI
September 13, 2026

Introducing the World’s First Clinical Finance AI Agent Purpose-Built for Biopharma

Today we unveiled Condor's Clinical Finance AI Agent — the world's first AI agent purpose-built for biopharma R&D finance.

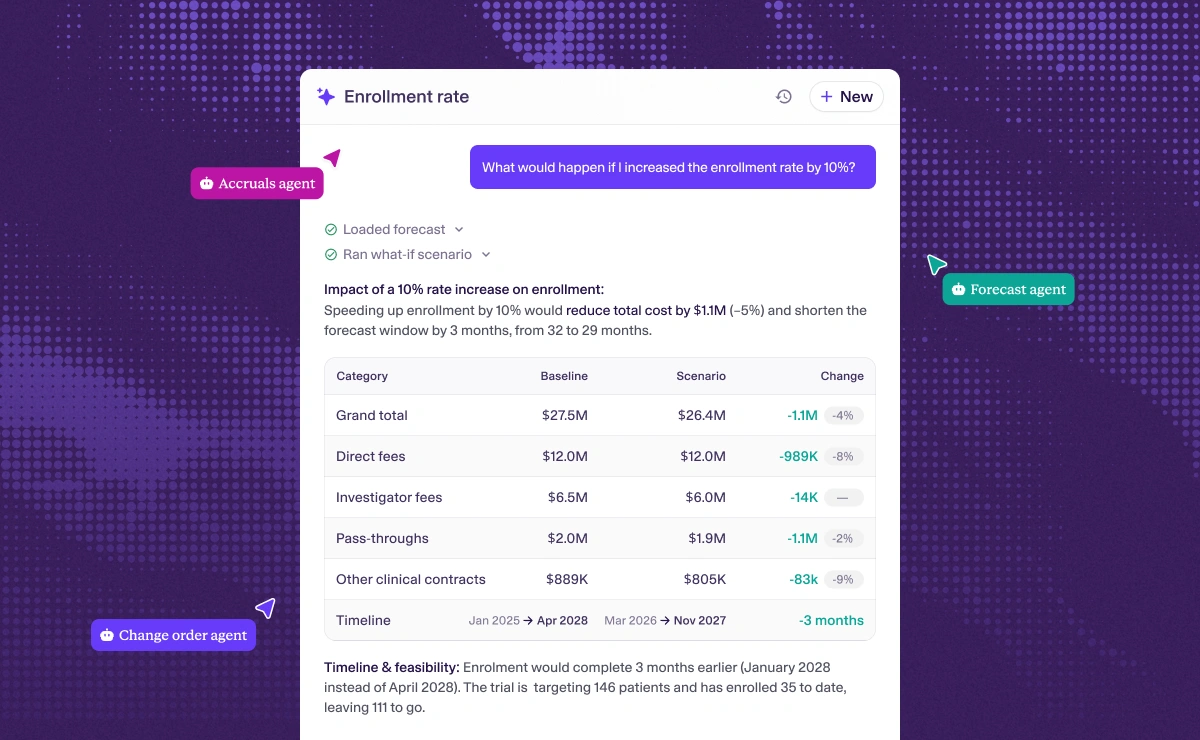
Ask it why a trial's actuals and forecast diverged, and it reasons across your full budget and forecast history to give you the answer in seconds, not the days it takes to reconcile across your ERP, CTMS, EDC, and a dozen spreadsheets. Ask it what a change in site mix or enrollment timing will cost you, and it runs the scenario and builds the resulting model directly in Condor. It doesn't just surface a number. It gives you the "why," and then it does the work.

This is a big milestone for our company and industry. It's also the moment I've been building toward since the day I started Condor.

The vision I had five years ago

When I founded Condor, I believed the financial machinery underneath every clinical trial could be fully automated, end-to-end, with AI reasoning on top of it. 

No more manually managing or outsourcing your finances. The numbers, built by an engine you can trust. Workflows run by AI. The why behind the numbers, uncovered in seconds instead of weeks, while there’s still time to act. 

Our new agent is the realization of that vision.

Why it took five years

Building AI that produces numbers you can actually trust is unbelievably hard. 

It took building Condor's financial engine first — a deterministic layer that follows defined rules, produces consistent output every time, and is fully auditable. No guessing, no black box, no "the model thinks it's probably right." Every number has to tie back to the clinical activity that actually drove it, because in this industry, a number nobody can defend is a number nobody will use.

It took building a knowledge graph grounded in a clinical and financial ontology we developed over years of work with Big 4 accounting firms — mapping how budgets, vendor contracts, clinical sites, and clinical activity actually connect to each other, across hundreds of studies and therapeutic areas. That ontology is what lets our agents understand a change order or a forecast variance the way a clinical finance team does, instead of the way a generic model guesses.

We built all of that first, five years ago, before there was a market pulling us to do it, because we knew it was the only foundation AI could stand on and still be trusted with a number that ends up in a board deck.

Recently, competitors that built their entire business model around outsourcing clinical finance — putting bodies behind the work instead of automating it — have realized AI is where our industry is headed. They're years behind, so the best they can offer is AI bolted on top of their services model. 

Layering AI onto a services model doesn't change what the AI is standing on. If the underlying data was never built for automation — if it was always meant to be assembled by a person — AI on top of it can move faster, but it can't reason with the same grounding as our AI platform. It will take those companies years to build what we have been building for the last five years, because an ontology and a knowledge graph like ours can't be retrofitted. They have to be the starting point.

Why our AI platform matters now, more than ever

For most of the last century, science was the bottleneck in drug development. AI is closing that gap fast, and pipelines are about to fill with more candidates than this industry has ever had to fund at once. Every one of those candidates still has to be forecasted, funded, and managed. Right now, the financial infrastructure doing that job is still, for almost everyone, a spreadsheet.

The bottleneck didn't disappear. It moved from the lab to the ledger. Today, Condor is the only platform built from the ground up to run biopharma R&D finance and operations at the scale AI-driven pipelines are about to demand. Because we built the engine, then the knowledge graph, then the agents, in that order, on purpose.

What comes next 

Our Clinical Finance Agent is one of a growing team of agents built on Condor's knowledge graph. Each one, including our forthcoming investigator grant agent, is purpose-built to remove a specific piece of manual work slowing R&D finance and clinical operations teams down.

My vision is here: No more manually managing your finances. The numbers built by our engine. The workflows run by AI. The why behind the numbers uncovered in seconds, not weeks, while there’s still time to act. 

This is the start of something big for our industry. 

If you want to see the agent for yourself, book a demo.

Read the article

AI
August 30, 2026

Reimagining Investigator Grants with AI

Here's what we keep hearing from clinical finance and ops teams: "I know we need to be doing something with AI. I just don't know how to start. Can you share practical, hands-on examples of how to use AI in clinical finance?" That question is why we kicked off our webinar series, Practical Applications of AI in Clinical Finance & Ops. It's built around one simple premise: real use cases, real workflows, real results. No theory, no hype, just what actually works.

Our first session tackled CRO change orders. Our latest webinar took on the biggest line item in almost every clinical budget: investigator grants.

Here's the webinar recording.

Why Focus on Investigator Grants?

Investigator grants aren't a line item you can afford to get wrong. On average, site payments for administrative fees and patient visits account for roughly 48% of total per-trial cost. The average investigator grant runs about $6,900 per patient across therapeutic areas, and oncology trials push that closer to $18,700 per completed patient. On a study of any real size, that's tens of thousands of individual transactions, each one needing to be verified against whether the activity actually happened and whether the invoiced amount matches what was contracted.

The people on the other end of those payments can't absorb your payment terms. Sites paid on a monthly cycle wait an average of 45 days to be reimbursed for work already performed. On quarterly terms, that stretches to 137 days, nearly three times the wait for the same work. Forty-three percent of sites report three months or less of operating capital in the bank, and CTTI estimates that 40% of site dropout is tied to payment delays. Twenty-three percent of sites report delays of 90 days or longer. Payment accuracy isn't a back-office hygiene issue. It's site relationship and enrollment risk.

Grants are also just structurally hard to get right. The activity and the money live in different systems: your EDC knows which visits happened, but finance typically only sees the invoice and payment files, with no line-by-line reconciliation between the two. Every site contract is its own snowflake of rates, invoiceable procedures, screen-fail caps, holdbacks, and overhead, all buried in contract PDFs that range from clean to, frankly, illegible. Protocols now average 3.3 substantial amendments, and each one can reprice visits and admin fees mid-study. And invoiceables like screen failures and unscheduled visits often accrue in the dark, surfacing all at once as a true-up at closeout instead of being tracked as they occur.

Most sponsors respond by outsourcing grants management to a CRO or payments vendor, and that's often the right call. CROs bring dedicated staff, global payment rails, and the ability to manage hundreds of site relationships at once so you don't have to build that function internally. But outsourcing the work isn't the same as outsourcing the accountability. Payments are frequently a low-margin, pass-through afterthought inside a much larger CRO contract, and you're trusting a vendor to approve, calculate, and report on its own work. When your auditors and your board have questions about the numbers, they're asking you, not your CRO.

We shared two stories from the field that show what happens when convenience wins out. In the first, a top-five global CRO replaced its investigator payments team with an automated pay platform that auto-paid every invoice it received. Sites started getting checks for patient visits that hadn't happened yet, and it took months to unwind the confusion. In the second, a mid-cap oncology sponsor closed out a trial and received a $5 million bill from its CRO for invoiceables that had never been tracked or accrued along the way. The money had already been spent; the sponsor was simply the last to find out. Automation without reconciliation just makes the wrong payment happen faster.

How to Reimagine Investigator Grants with AI

To show what's actually possible today, we ran the same investigator grant payment report through two very different tools: Microsoft Copilot, something most finance teams already have access to, and Condor's purpose-built platform.

Using Microsoft Copilot

Jeff started by dropping a CRO investigator grant payment file, covering the last two quarters of a phase 3 study, into Copilot with the following prompt:

I'm the head of clinical finance at a biotech company. Attached is the investigator grant payment report from our CRO for our phase 3 study covering the last two quarters. Please analyze it and give me: total payments by site and month, highlighting the five highest-paid sites; a breakdown of visit payments versus procedures versus invoiceable pass-through line items; any payments that look inconsistent with each site's contract budget or with the visits patients actually completed; what we should accrue for work sites have performed but not yet been paid for; and five questions I should ask the CRO before approving the next payment run. Format the output as a brief memo I can share with my CFO.

Two things make this prompt work. First, it's specific about exactly what the output should contain, since a general ask invites the model to fill gaps with something that merely looks credible. Second, it gives the model context on audience and intent, telling it who's asking and who the memo is for, so it knows what level of detail and framing to use.

Copilot came back with a clean executive summary: roughly $270,000 in payments, weighted toward startup activity and pass-through costs consistent with early enrollment, no obvious duplicate payments, but several items flagged for CRO follow-up. It broke out the top five paid sites, plotted payments by month, and split the mix between visits, procedures, and invoiceable pass-throughs. It flagged a 4-5 month lag between when sites performed visits and when they were reimbursed, and called out specific items, like a biopsy and imaging reimbursement paid before the associated screening visit, and ECG charges appearing months after their related visits.

For a tool that's already sitting in most people's Microsoft 365 license, that's a genuinely useful starting point: a fast, readable summary, clean per-site totals, catches on the obvious duplicates and outliers, and a CFO-ready memo in seconds with zero procurement.

But here's where it stops. Copilot can't see the EDC, so it can't tie a payment to a visit that actually happened. It doesn't know the contracted rates, caps, holdbacks, or overhead in the site agreements, so it has no way to know whether a flagged charge is actually wrong. The accrual figure it generates is an extrapolation of past payments, not a measurement of completed activity, and it can't distinguish an early payment from an unearned one. Run the same prompt twice and you may get a different answer, with no evidence trail behind either one. It reads the payment file. It cannot read the trial.

From "What the File Says" to "What's True": The Condor Demo

Nim then walked through the same investigator grant scenario inside Condor. Instead of reasoning from a single spreadsheet, Condor's Intelligence Engine reconciles patient-level activity, visits, procedures, and site admin fees coming from the CRO, directly against the EDC data sponsors already have, using AI to map each payment to the business context behind it. The system proposes the mapping automatically; nothing overrides a user's judgment without review, but the matching itself doesn't require anyone painstakingly reconciling line by line.

Once that file is imported, two things change. The overview surfaces CRO and site performance alongside payment reconciliation, flagging missing invoices and overbilling immediately and pointing to which sites need attention. And a trend layer goes beyond flagging individual discrepancies to surface patterns: what share of spend is startup versus investigative, which sites show unusual or no activity, and how performance is trending over time, the exact kind of history and pattern-matching a generic LLM has no way to see. From there, users can drill into the raw patient data, overlay it against processed EDC data in native currency or USD, and investigate a specific negative variance down to the site, visit, procedure, or admin fee level.

The platform is built around four core principles: the full story lives in one place instead of scattered across systems; overbilling, missing invoices, and pricing issues are visible at a glance instead of requiring a manual dig; discrepancies and off-contract charges are flagged as they appear; and everything is oriented toward decision support, so teams spend less time combing through data and more time acting on it.

Mapped back to the two stories from earlier in the session: the auto-pay trap becomes activity matching, every payment tied to a corresponding EDC event, so a payment with no visit behind it is caught before it goes out the door instead of after. And the closeout surprise becomes continuous invoiceables tracking, watching that spend accrue monthly as it happens, so it becomes a line item you tracked all along rather than a bill that shows up at the end.

What We Heard From the Room

Several attendees asked some version of, "If I upload my EDC and contract data into Copilot and structure the prompt correctly, can't I get there myself?" Short answer: to a point, yes, but volume becomes the constraint fast. Most general-purpose tools cap how many documents you can attach to a single prompt, well short of the dozens or hundreds of contracts a real trial generates. Without a knowledge graph or ontology behind it, there's no guarantee you get the same answer twice.

On data sources, Condor works from whatever level of detail a CRO provides, whether that's an accrual report or the underlying invoices, and the more detail available, the more granular the mapping. Unmapped invoiceables and procedures are clearly flagged in the reconciliation table so they can be reviewed and remapped rather than silently dropped. Protocol amendments are handled by loading the full history of a site's CTA, so a visit performed before an amendment's effective date is recognized at the old rate and everything after at the new one, even across sites with seven or eight amendments over a study's life. The platform supports full multi-currency and FX conversion, any therapeutic area, and, per attendees who asked directly, no cap on site count. Some phase 3 oncology trials on the platform run 500-plus sites, each with its own contract history, and international sites are handled the same way as domestic ones, loaded through automation and human-in-the-loop review into the same normalized EDC and contract structure.

What's Next in the Series

This is only our second session, and we've already received multiple topic ideas from attendees. Our next webinar will be in early October, and we’ll share the topic soon. 

In the meantime, if you'd like to see what Condor can automate for your investigator grants process specifically, book a demo with our team here.

Read the article

AI
July 26, 2026

Reimagining CRO Change Order Management with AI

Here’s what we keep hearing from clinical finance and ops teams:

"I know we need to be doing something with AI. I just don't know how to start. Can you share practical, hands-on examples of how to use AI in clinical finance?"

The answer is yes, absolutely. To help, we’ve kicked off a series we call Practical Application of AI in Clinical Finance & Ops. It’s built around one simple premise: real use cases, real workflows, real results. No theory or hype. Just what actually works.

Our first webinar focused on the three levels of AI maturity, the AI mindset teams must have to successfully implement and scale AI, and how AI is evolving and what that means for pharma clinical finance and ops teams. 

Our latest webinar focused on reimagining CRO changes order management with AI. 

Why Focus on CRO Change Orders?

If you work in clinical finance or clinical operations, you don't need convincing on this one. Change orders are one of the most painful, recurring problems, and the data backs up what everyone already feels. Substantial protocol amendments, which are the main trigger for change orders, have gone from affecting 57% of trials a decade ago to 76% today. In Phase 3, it's 82%. On average, a Phase 3 change order runs $535,000, which is close to four times the Phase 2 figure, and takes about three months to negotiate.

Scale that across a typical portfolio, say eight active studies, and you're looking at 40 to 50 change orders across the portfolio, including ancillary vendors. That represents $10 million or more in unplanned, unbudgeted costs. Meanwhile, change order volume has roughly doubled over the past decade, while finance headcount at a typical biotech has stayed flat. That gap gets closed one of three ways: with tooling, headcount, or with weekends.

On top of the volume problem, change orders are just hard to review. The explanations on each line item are often a sentence or two. CROs sometimes lowball the initial bid, knowing the change order process is where they recover margin. And retrospective work, cost for activity that already happened, routinely shows up buried in a document you're given a week or two to evaluate. It's a lot of financial exposure moving through a process with very little tooling behind it. That combination of high stakes and low tooling made it the obvious place to start.

How to Reimagine Change Order Management with AI

In the webinar, we walked through the same change order budget three different ways: first with generic AI, Microsoft Copilot. Then with Condor's purpose-built AI, Talon. And finally by flipping the process entirely and modeling the scope change in Condor before the CRO's document even arrives.

Using Microsoft Copilot

One of the most common requests after the panel was for something people could go use immediately. If you have Microsoft 365, you already have Copilot, and that's genuinely a useful starting point for a first pass at any change order. Here's the exact prompt we used in the webinar:

"I'm a finance director at a biotech company. I've received the attached change order budget from a CRO for a Phase 3 study. Please analyze it and give me a summary of the total cost change and the top five largest cost increases, a breakdown of direct fees versus pass-through costs versus investigator costs, any line items that appear to be retroactive or cover work already performed, and a list of five questions I should ask the CRO before approving this change order. Format the output as a brief memo I can share with my CFO."

A few things worth noting about why this prompt works: it gives the model a role ("I'm a finance director"), a specific task, and a defined list of deliverables. The more context you give a general-purpose model before you hit send, the better the output. Attach your change order file, run this, and in under a minute you'll have a readable first-pass memo.

Just know where it stops. A general-purpose tool can tell you what a document says. It can't tie units back to your original contract, it has no knowledge of your protocol history, and it won't reliably catch unlabeled retroactive work. It gets you from zero to informed. It doesn't get you to defensible. That's the gap purpose-built, ontology-driven tools like Talon are built to close, and it's why the answers looked meaningfully different once we ran the same budget through a model that actually understood the contract underneath it.

From "What Changed" to "What's Wrong": The Talon Demo

That's the gap we closed with the next demo. I ran the exact same change order budget through Talon, an AI-powered service offering we’re rolling out to customers, which has our clinical and financial ontology built into it. Instead of just summarizing what changed, Talon made judgment calls on every line item: it flagged that roughly 94% of the total dollar delta was unjustified, inadequately supported, or needed clarification, and sorted every line into a clear disposition, hard no, negotiate, needs clarification, or accept. It landed on a negotiation target of $1.4 to $1.7 million in recoverable savings, with a realistic settlement range of $556,000 to $856,000 given how CROs typically respond to pushback.

The reasoning behind that is what makes it useful. On the largest cost driver in the change order, added monitoring visits, Talon explained that monitoring spend is mechanically tied to patient volume, not site count, and since patient counts hadn't changed, the increase didn't hold up. It reverse-engineered the expected cost from the original contract's drivers (per-patient procedures, per-site fees) and showed the gap between that and what the CRO was billing, with every finding linked back to the source cell in the change order budget grid. Microsoft Copilot told us what the document said. Talon told us what it was hiding, and gave us a negotiation brief to send back to the CRO.

Getting Ahead of the Change Order Entirely: The Condor Scenario Planning Demo

The last demo flipped the sequence altogether. Instead of waiting for a CRO's change order and then analyzing it, I modeled the scope change myself, before any document arrived, directly in Condor's production environment. I typed a plain-language prompt asking the system to forecast a scenario for the study: expand from seven to 11 sites, keep the 48-month duration and hold patient counts flat, then show the incremental cost against the current $10.67 million contract value.

Condor's forecasting agent built that scenario in real time, referencing the study's actual contract structure and cost drivers, and landed on a $629,000 incremental increase. Compare that to the $2 million-plus the CRO's change order was requesting for the same scope, and the gap tells you everything: once you strip out costs that shouldn't move when patient volume doesn't (like a big chunk of that monitoring spend), the real cost of the change is a fraction of what was billed. That's the value of scenario planning: you walk into the negotiation with your own independent number already in hand, instead of reacting to whatever number the CRO sends first.

Here’s the webinar recording.

We’ve trimmed the Talon and Condor demos from it. Want to see all the demos, and see what this looks like with your own data? Book a demo with our team here.

What's Next in the Series

As I mentioned, this is the second of several webinars and workshops in our Practical Applications of AI in Clinical Finance & Ops series. We polled attendees live during the webinar on what they wanted to see next, and the results were clear. Here are a few of the topics we’ll cover:

  • Monitoring vendor spend pacing against contract value and identifying anomalies in vendor invoices (the top pick)
  • Building a first trial budget from a protocol
  • Building an AI prompt library for your clinical finance team

We'll be running these both as webinars and as in-person live workshops at upcoming industry events, where you can bring your laptop and work through the exercises with us in real time. Stay tuned for updates!

Read the article